
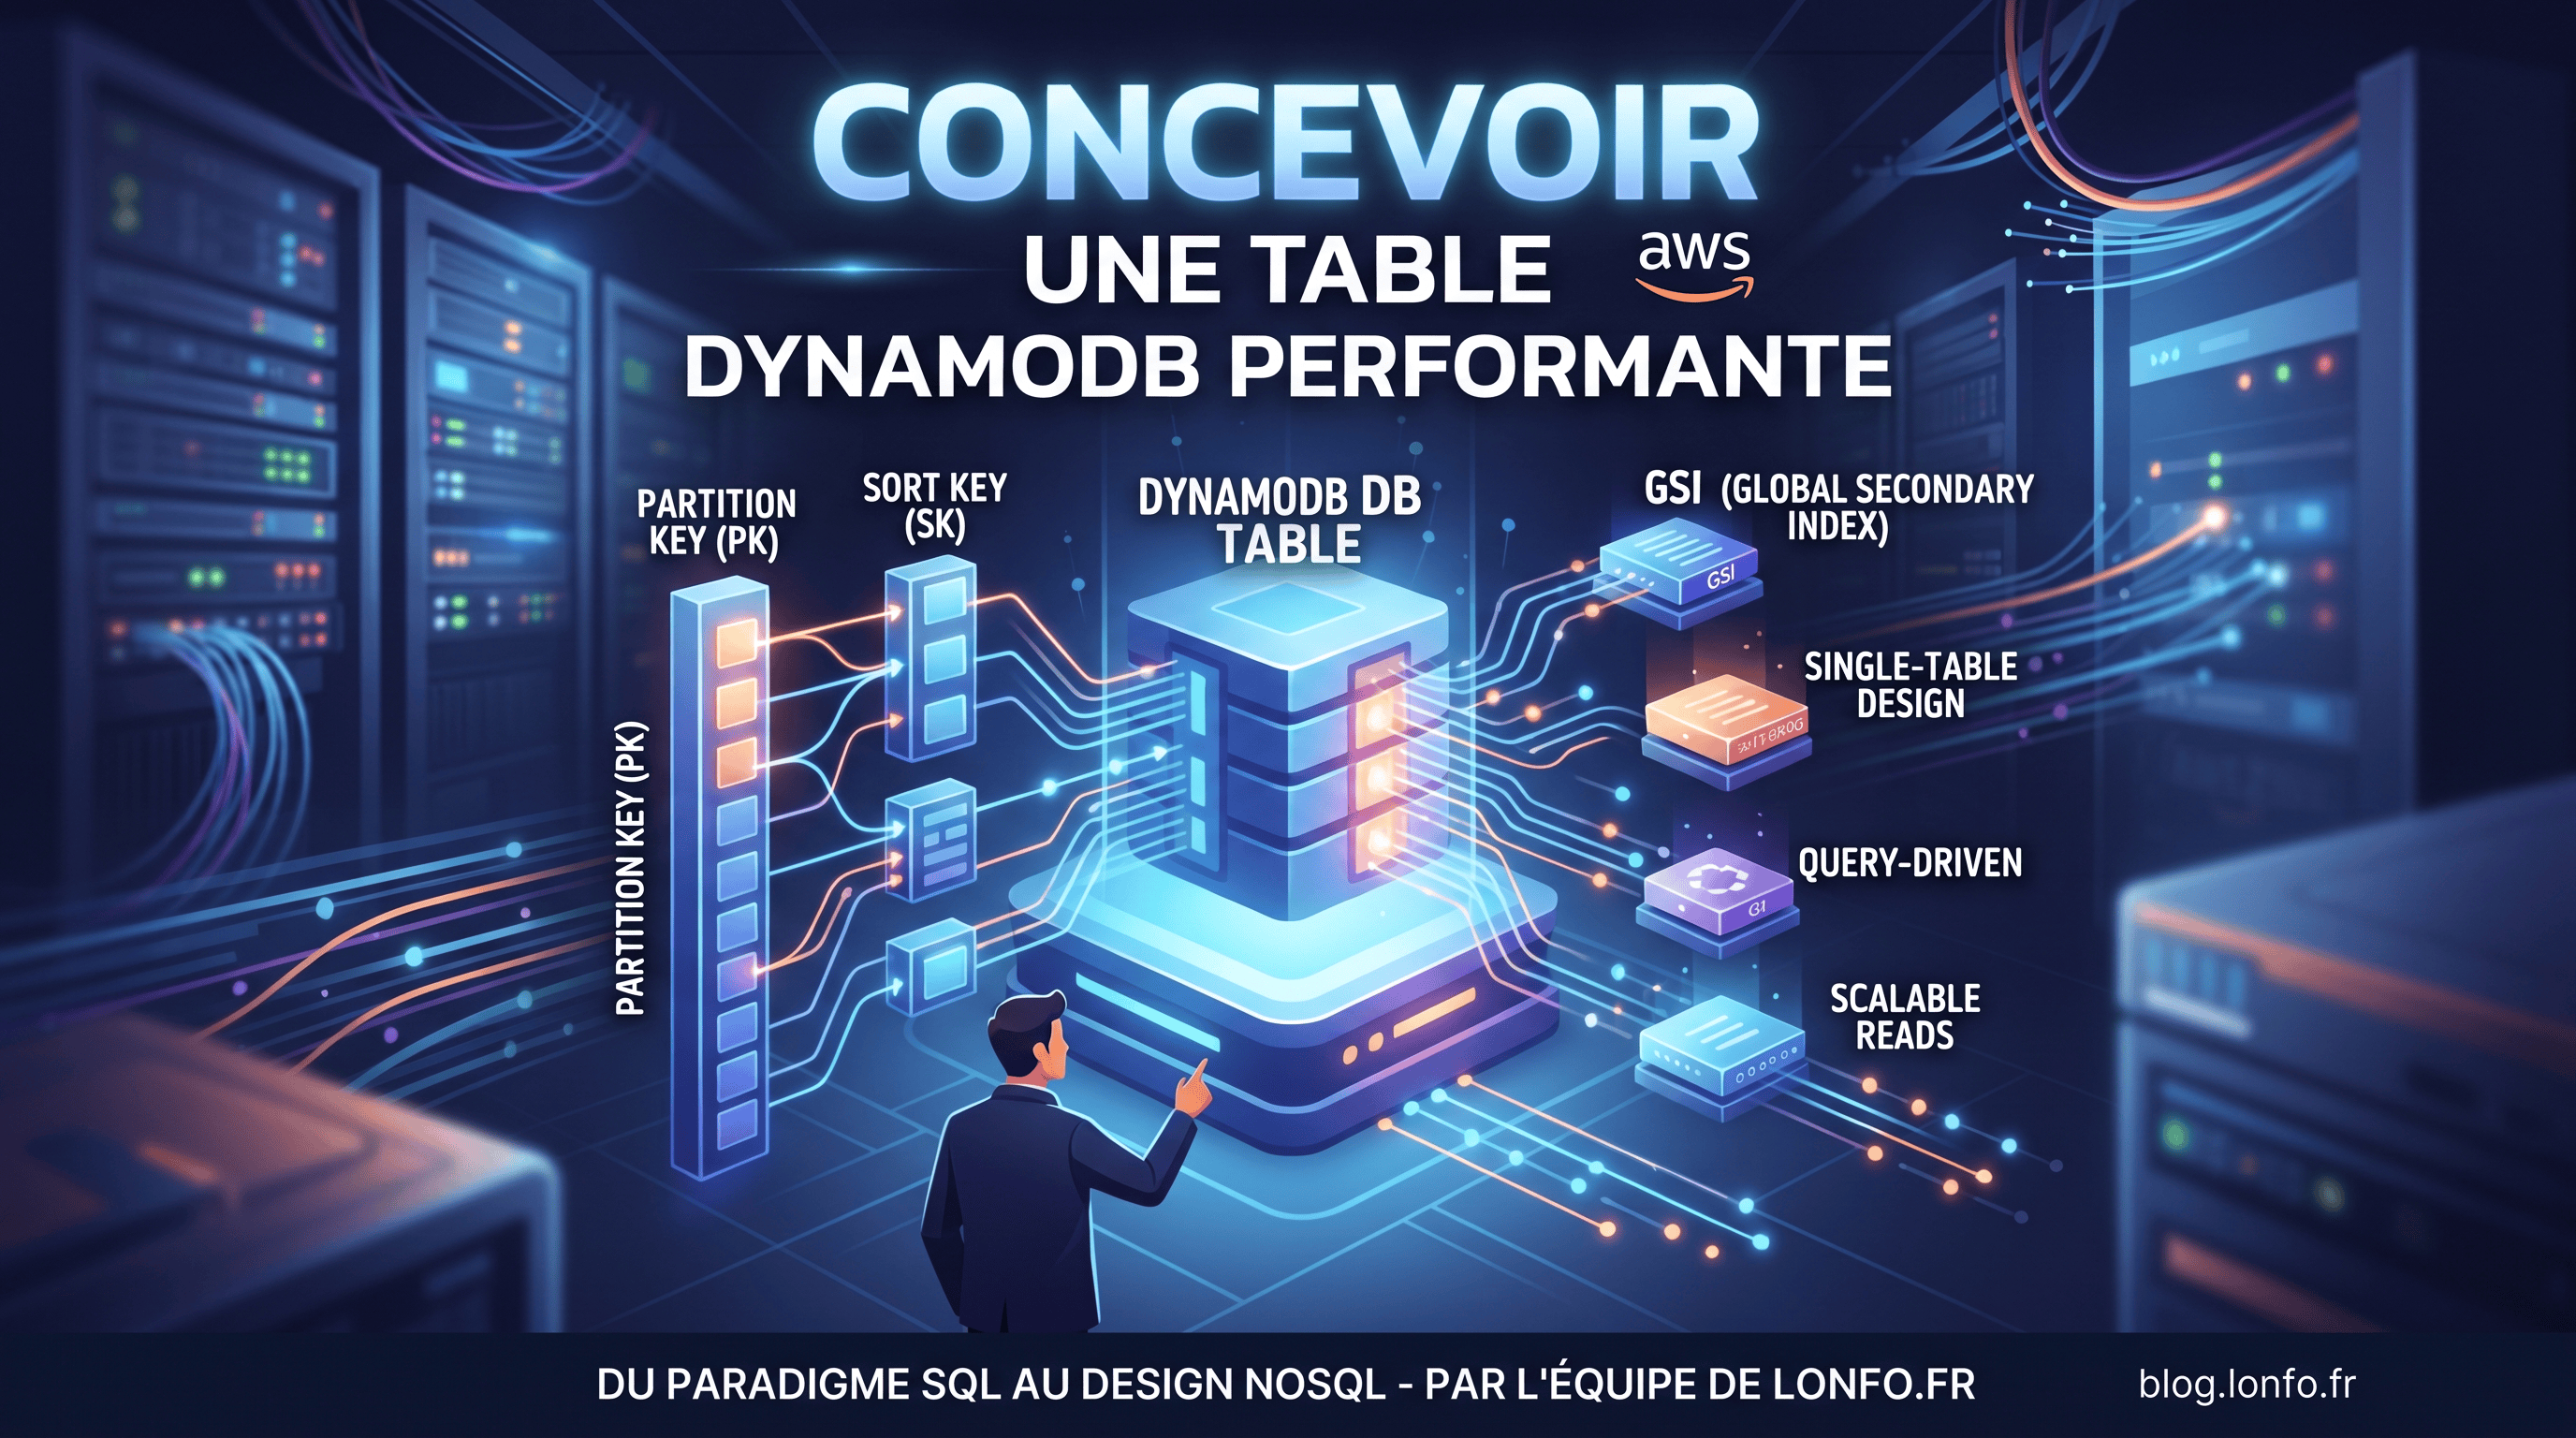
How to Design a High-Performance DynamoDB Table?
Introduction
If you are coming into the world of DynamoDB with a relational background (PostgreSQL, MySQL, Oracle), forget everything you know. The first mistake 90% of developers make is designing a NoSQL database like a SQL database: creating tables per entity, excessively normalizing, and hoping to run clean JOIN later.
Result? It is a guaranteed crash in production: collapsing performance, exploding AWS costs, and impossible queries.
Unlike relational databases, DynamoDB was designed for one single thing: delivering ultra-fast and predictable performance (in milliseconds, or even microseconds), regardless of scale, from the first to the billionth user. To achieve this, the paradigm shifts completely: you move from a data-centric design to a query-driven design.
By the end of this article, you will know exactly how to model your DynamoDB tables like a cloud architect.
1. The Big Paradigm Shift: SQL vs DynamoDB
To understand how to design a DynamoDB table, you must first understand why SQL doesn’t work here.
In SQL (Relational): Normalization and Joins
In SQL, you optimize storage. You split your data across multiple tables to avoid duplication: a users table, an orders table, an order_items table.
- The principle: You store data cleanly, and the database figures out how to piece it back together on the fly when you run your query, using
JOINs. - The problem with NoSQL: DynamoDB does not support joins. If you have to cross three tables to render a simple profile page, you will have to make three separate network requests, which ruins the speed advantage of NoSQL.
In NoSQL / DynamoDB: Denormalization and Single-Table
In DynamoDB, you optimize reads.
The opposite principle: You duplicate data. You accept storing the same information multiple times if it allows you to retrieve it in a single, unique operation (called a Query or GetItem).
The absolute goal: Obtain all the data required to render an application view with a minimum of network calls to the database.
2. Step 1: Analyze Access Patterns (Query-Driven Design)
This is the golden rule, the number one commandment of DynamoDB: Never start by designing your tables or columns. If you start by saying, “I’m going to create a User table with a name, an email, and a creation date,” you’re doing it wrong. You must start by listing all the questions your application will ask the database.
Practical Method:
Take a piece of paper (or a mind-mapping tool) and write down all your Access Patterns. For example, for an e-commerce application, your list might look like this:
- Retrieve user information using their ID.
- List all orders for a user, from newest to oldest.
- Find the details of a specific order via its ID.
- List available products in a given category.
Why is this vital?
In DynamoDB, you build your data structure based on the questions you will ask it, rather than the intrinsic nature of the objects. If a new access requirement arrives later and wasn’t anticipated, a complete redesign of the modeling may sometimes be necessary.
3. Step 2: Choose Primary Keys
Once your Access Patterns are listed, you must design the primary key of your table. This is DynamoDB’s internal search engine. Unlike SQL where you can filter on any column without much thought, DynamoDB relies entirely on its primary key to physically locate where data resides. You have two main choices:
A. Simple Partition Key (HASH)
This is a unique identifier (e.g., a userId or a productId).
How does it work? DynamoDB passes this value through a hash function to determine exactly which physical server (partition) holds the data.
The trap to avoid: Cardinality. Your partition key must have a large number of possible and unique values. If you use an attribute like
statuswith only two values (ACTIVEorINACTIVE), all your data will pile up on the same servers, creating what is called a Hot Partition (a critical overload of a portion of the database).
B. Composite Key: Partition Key + Sort Key (RANGE)
This is where DynamoDB becomes extremely powerful. By combining a Partition Key and a Sort Key, you create a storage hierarchy.
- The principle: All items sharing the same Partition Key are stored physically together, and sorted in alphabetical or numerical order according to the Sort Key.
- Perfect use case (e.g., a user’s orders):
- Partition Key:
USER#123 - Sort Key:
ORDER#2026-06-01T12:00:00Z - Thanks to this, a simple query on
USER#123allows you to instantly retrieve all orders for that user, sorted by date, or filter by date ranges (BETWEEN) with formidable efficiency.
- Partition Key:
- Perfect use case (e.g., a user’s orders):
4. Step 3: Use Secondary Indexes to Multiply Access Paths
You realize this quickly: with a single primary key (even a composite one), you can only answer a limited number of your Access Patterns. What if you need to look up a user by their email when your main table is organized by userId?
This is where Secondary Indexes come in. DynamoDB offers two types:
A. LSI (Local Secondary Index)
- Definition: An index that shares the same partition key as the base table, but uses a different Sort Key.
- Constraint: It must be created strictly at table creation time and shares global storage capacity. They are rarely used today in favor GSIs.
B. GSI (Global Secondary Index) — The Ultimate Weapon
Definition: A GSI is essentially an independent “second virtual table.” It has its own Partition Key and Sort Key completely decoupled from the main table.
How it works: DynamoDB asynchronously replicates data from your main table to the GSI as soon as a write occurs.
Example:
- Main table optimized for: Finding an order by
userId. - GSI created for: Finding an order by
emailDuClient.
- Main table optimized for: Finding an order by
Cost awareness: Each GSI has its own read/write capacity units (RCU/WCU) and duplicates storage space. They should only be created for strict and essential Access Patterns.
5. Step 4: Advanced Modeling Patterns
Once you master the basics, you can push DynamoDB logic to its peak with cutting-edge architectures.
A. Single-Table Design (The Cathedral of NoSQL)
In complex applications, the strong trend is to store all application entities in a single and unique DynamoDB table (users, orders, products, invoices).
- How? By using generic key names (
PKandSK) and prefixing data. For example:- A user:
PK=USER#123,SK=METADATA - An order for this user:
PK=USER#123,SK=ORDER#9988
- A user:
- Why? This allows you to retrieve the user profile and their orders in a single request (Batch or Query on the same partition), eliminating network latency. It is fiercely performant, but requires absolute design rigor.
B. Sparse Indexing
A GSI only indexes items in the table that contain the attributes defined for the index key. If an item does not possess that attribute, it is simply ignored by the GSI.
- Pro tip: This allows you to create extremely lightweight and ultra-fast indexes to isolate a subset of data (for example, only user accounts with a
PENDING_VALIDATIONstatus), drastically reducing storage and read costs.
Fatal Errors to Avoid
Before pushing your code to production, verify you are not making one of these classic mistakes:
- The
ScanTrap: TheScanoperation traverses the entirety of your table, item by item, to find what you are looking for. It is the equivalent of aSELECT * FROM tablewithout a WHERE clause in SQL. On a growing table, this will saturate your database, explode your AWS bill, and render your application unusable. Always useQueryorGetItemvia keys and indexes. - Neglecting Item Size (400 KB Limit): An item (a row) in DynamoDB cannot exceed 400 KB. If you use Single-Table Design and try to embed infinite lists (e.g., all comments of a blog post stored in the same item), you will block your application the day that threshold is crossed. For large volumes, prefer storing heavy elements in Amazon S3 and keeping only the URL in DynamoDB.
Conclusion
Designing a DynamoDB table requires a true shift in perspective: the application dictates the structure of the database, not the other way around. In summary, to succeed in your design every time:
- Precisely list all your access needs before coding.
- Define an intelligent composite primary key if you need relationships or sorting.
- Add GSIs targeting only essential secondary queries.
- Permanently ban
Scanoperations. Once these reflexes are acquired, DynamoDB becomes one of the most enjoyable and scalable tools in the cloud ecosystem.

Comments